
AgentQL
Query web data and locate page elements by meaning with Python, JavaScript, Playwright, and a REST API.
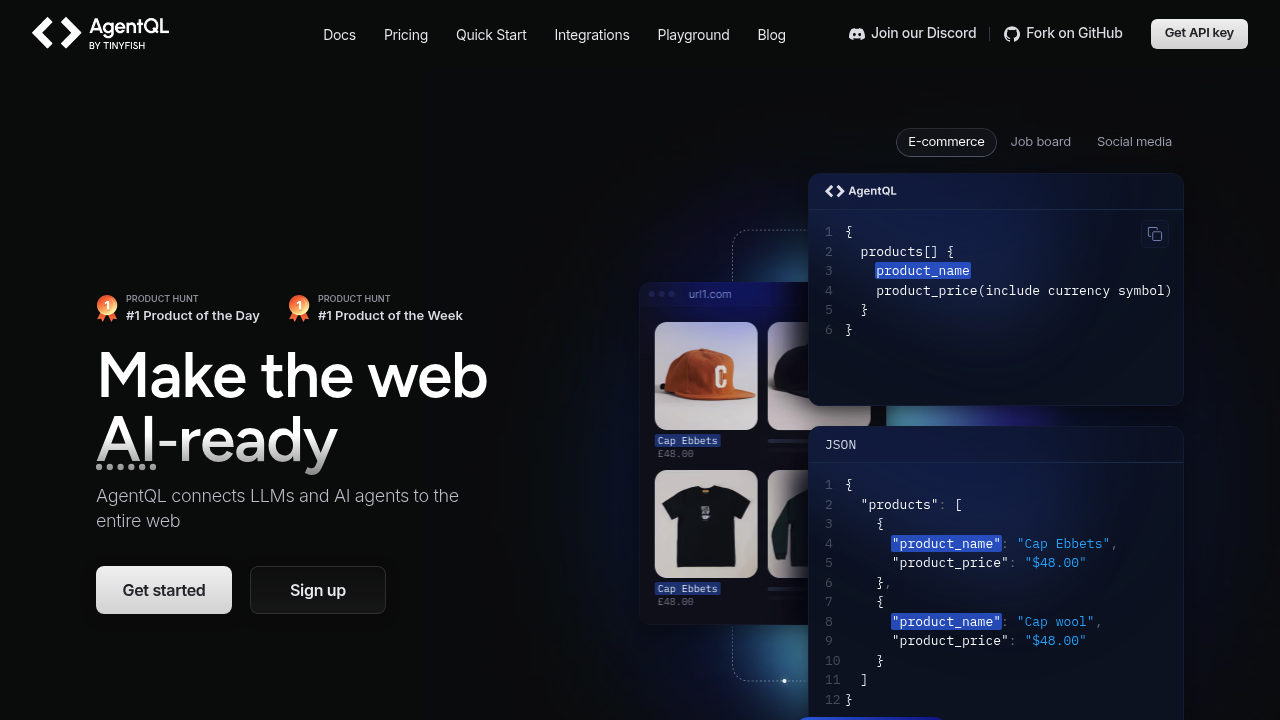
AgentQL is TinyFish's toolkit for extracting web data and interacting with page elements. Developers describe the fields or controls they need with a query instead of maintaining only CSS or XPath selectors. The returned structure can feed an AI agent, a data pipeline, or a browser automation script.
Key Highlights
- Semantic queries for data and page elements
- Python and JavaScript SDKs with Playwright
- Structured JSON shaped by the query
- REST extraction without a local browser
- PDF parsing and a browser query debugger
What Makes It Different
Meaning-based element selection reduces dependence on a particular page layout. A query describing products and prices can be reused on similar pages, while the service identifies matching content. That is a different approach from hard-coded DOM paths, but returned fields still need checking when labels or page meaning are ambiguous.
Features & Capabilities
Define the output shape, run a query against a page, and use the resulting values or element references in the next step. SDK workflows can interact with authenticated pages through a browser context. The REST API targets publicly accessible data without requiring the developer to manage a browser locally.
The debugging extension and playground help refine queries before a workflow runs repeatedly. PDF parsing extends extraction to documents, including tables. AgentQL is a distinct developer product from the broader TinyFish company and its other services.
User Ratings and Testimonials
Vendor-published testimonials from Heal.dev and Hove describe less parsing work and reusable extraction queries. These are customer accounts, not a universal accuracy benchmark. Test missing fields, dynamic content, and repeated layouts against a known result set before depending on unattended extraction.
Pricing & Value
- Trial: 300 free API calls and one remote-browser hour.
- Starter: $0/month, 50 monthly API calls, then $0.02/call; 10 included browser hours, then $0.12/hour.
- Professional: $99/month, 10,000 calls and 500 browser hours; overages cost $0.015/call and $0.10/hour.
- Enterprise: custom managed deployments.
Budget for both query calls and remote browser usage. The introductory trial differs from Starter's recurring allowance.
You might also like
 bisibility — Free beta: Track your website’s keywords, Google rankings, Search Console insights, and share of voice.


