
Together AI
Together AI gives developers inference, fine-tuning, and GPU clusters for open-source model apps.
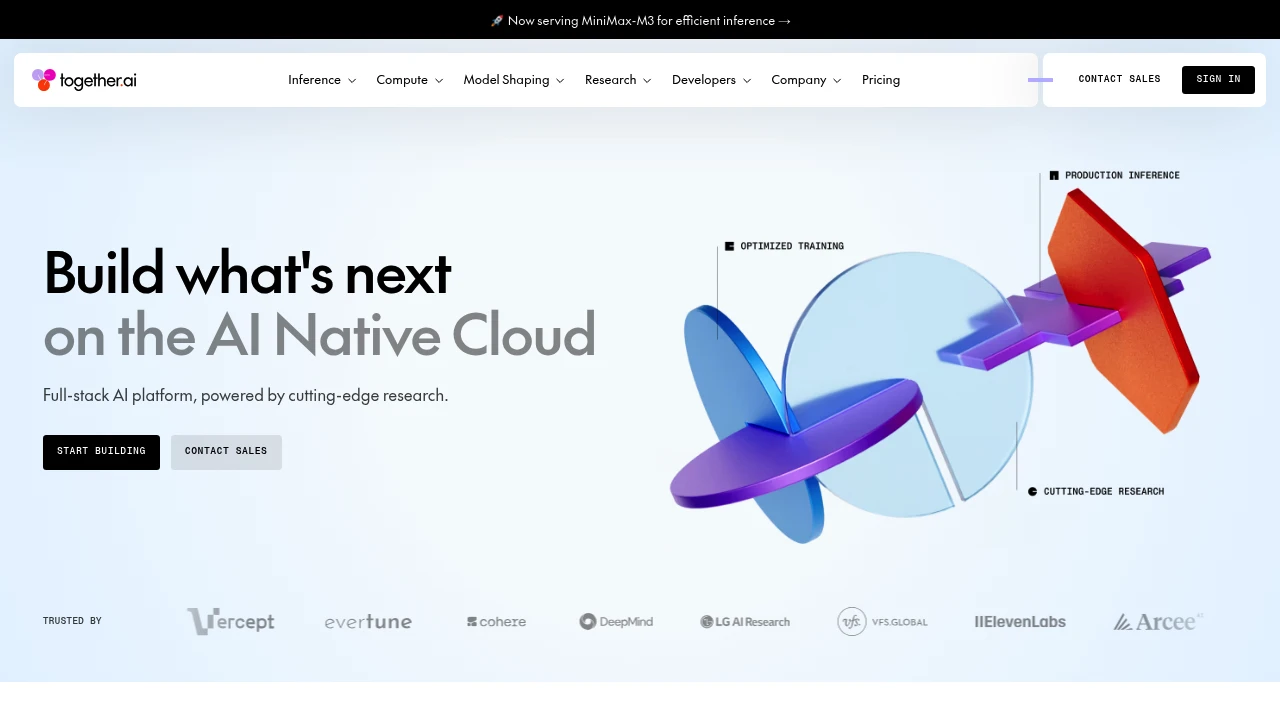
Together AI is an AI infrastructure cloud for teams building with open-source models. It combines inference, fine-tuning, GPU clusters, storage, and code sandboxes in one developer platform.
Key Highlights
- Serverless Inference for open-source models with no infrastructure to manage
- Batch Inference for asynchronous jobs, described at up to 30 billion tokens per model
- Dedicated Inference and containers for single-tenant model and media workloads
- GPU Clusters with NVIDIA H100, H200, and B200 capacity
- Fine-Tuning, Sandbox, and Managed Storage for model shaping, code execution, and storage
What Makes It Different
Together AI combines broad infrastructure with systems research. Its site claims 2x faster inference, 60% lower cost, and 90% faster pre-training through workload-specific optimization and the Together Kernel Collection. Instead of selling only an API, it lets teams move from serverless inference to dedicated endpoints or reserved clusters.
Features & Capabilities
Developers can run models on demand, submit batch jobs, deploy dedicated endpoints, or use containers for generative media. Compute spans self-serve clusters to thousands of GPUs, with object storage, parallel filesystems, and zero egress fees.
For model shaping, Together AI supports fine-tuning open-source models. The site says this can improve accuracy, reduce hallucinations, and control behavior without managing training infrastructure. Sandbox adds secure code execution and development environments.
User Ratings and Testimonials
Together AI publishes customer stories, including Cursor and Decagon. These are selected examples rather than an independent average rating. The main buying caution is billing: estimates may combine token rates, GPU hours, sandbox compute, storage, and fine-tuning tokens.
Pricing & Value
Self-serve access uses prepaid credits: a minimum $5 purchase and positive balance are required. Together AI does not currently offer free trials. Published usage rates include:
- Serverless Inference: per 1M tokens, MiniMax M3 costs $0.30 input/$1.20 output; Gemma 4 31B costs $0.39 input/$0.97 output
- Dedicated Inference: HGX H100 at $5.49 per GPU/hour and HGX B200 at $8.99 per GPU/hour for on-demand endpoints
- GPU Clusters: on-demand HGX H100 at $3.99, HGX H200 at $5.99 and HGX B200 at $8.19 per GPU/hour
- Sandbox and Storage: $0.0446/hour per vCPU, $0.0149/hour per GiB RAM, $0.03 per 60 minute code session, and $0.16/GiB/month storage
- Fine-Tuning: Llama 3.1 8B costs $0.34/1M training tokens for LoRA or $0.38/1M for full fine-tuning, with a $4 minimum job charge


FAQs
It provides AI cloud infrastructure for running, fine-tuning, and scaling open-source models through inference APIs and GPU clusters.
No current free trial is offered. Self-serve access requires a minimum $5 prepaid-credit purchase and a positive credit balance.
It is a private AI infrastructure company. Judge it by latency, model coverage, uptime, support, and total cost for your workload.
Its February 2025 Series B was led by General Catalyst and co-led by Prosperity7, with investors including Salesforce Ventures and NVIDIA.
You call its APIs or deploy dedicated GPU infrastructure, then choose serverless inference, batch jobs, fine-tuning, storage, or clusters.
Tags:
You might also like
 bisibility — Free beta: Track your website’s keywords, Google rankings, Search Console insights, and share of voice.


